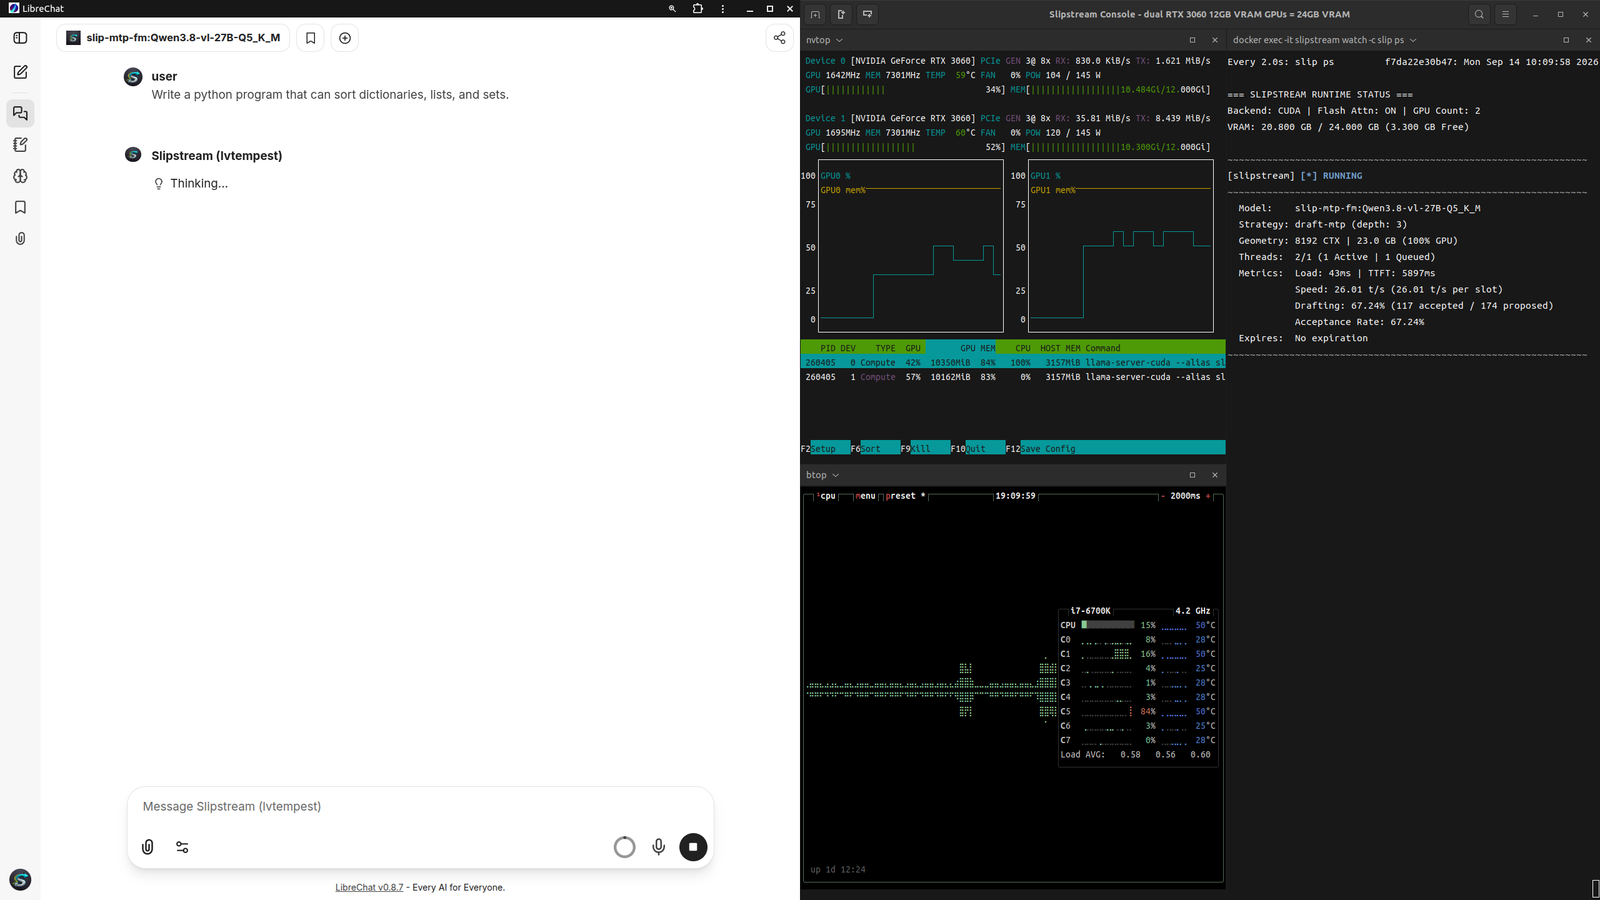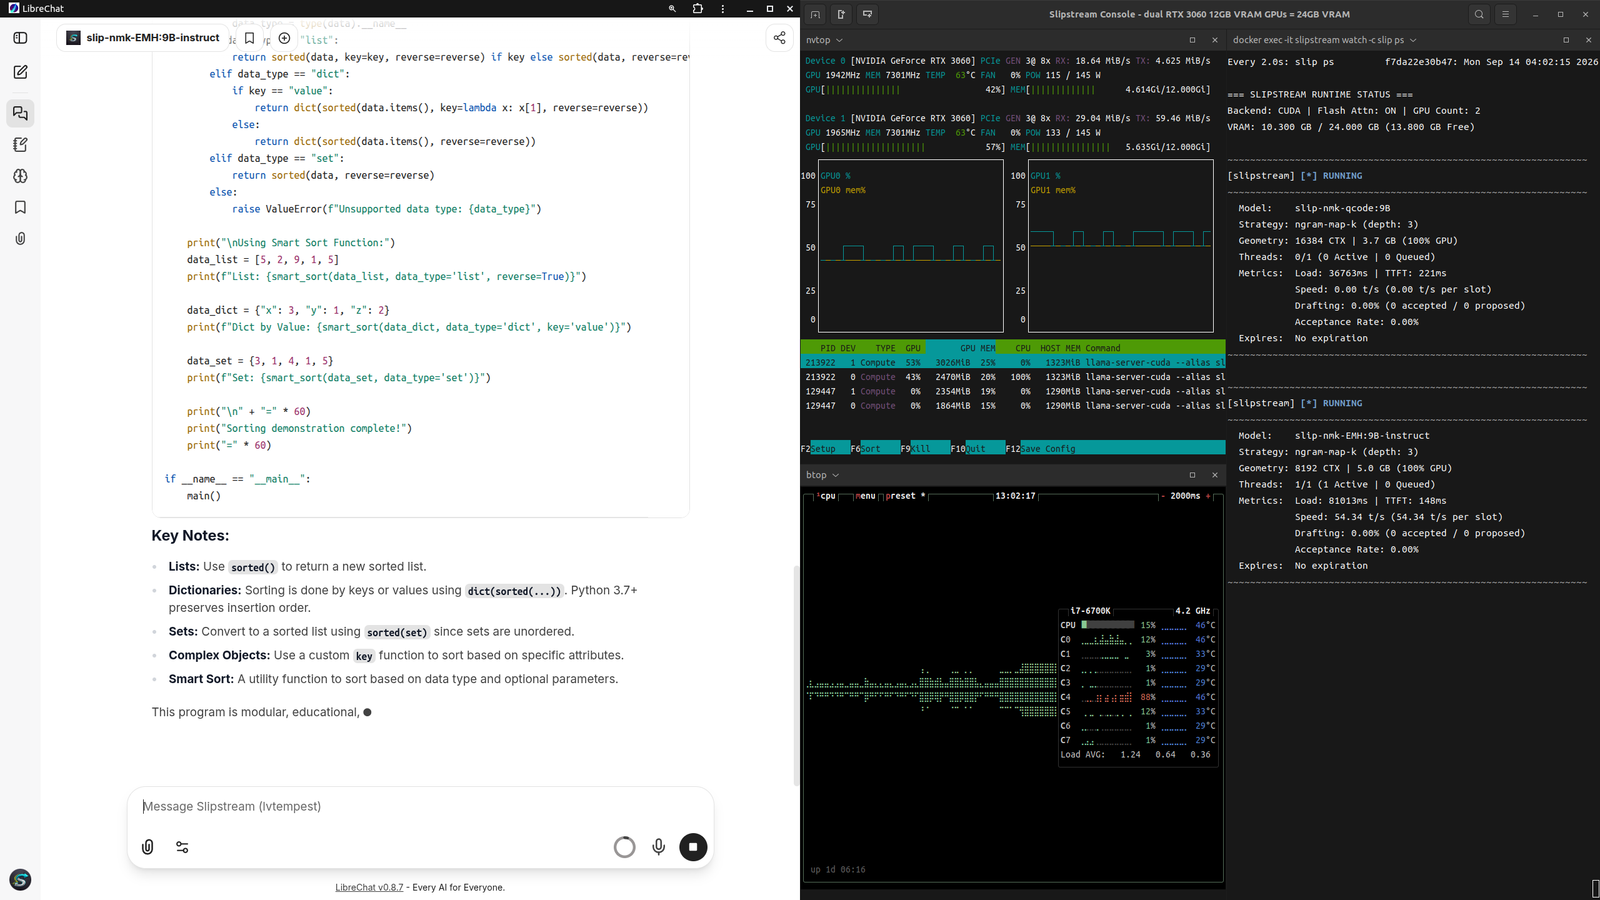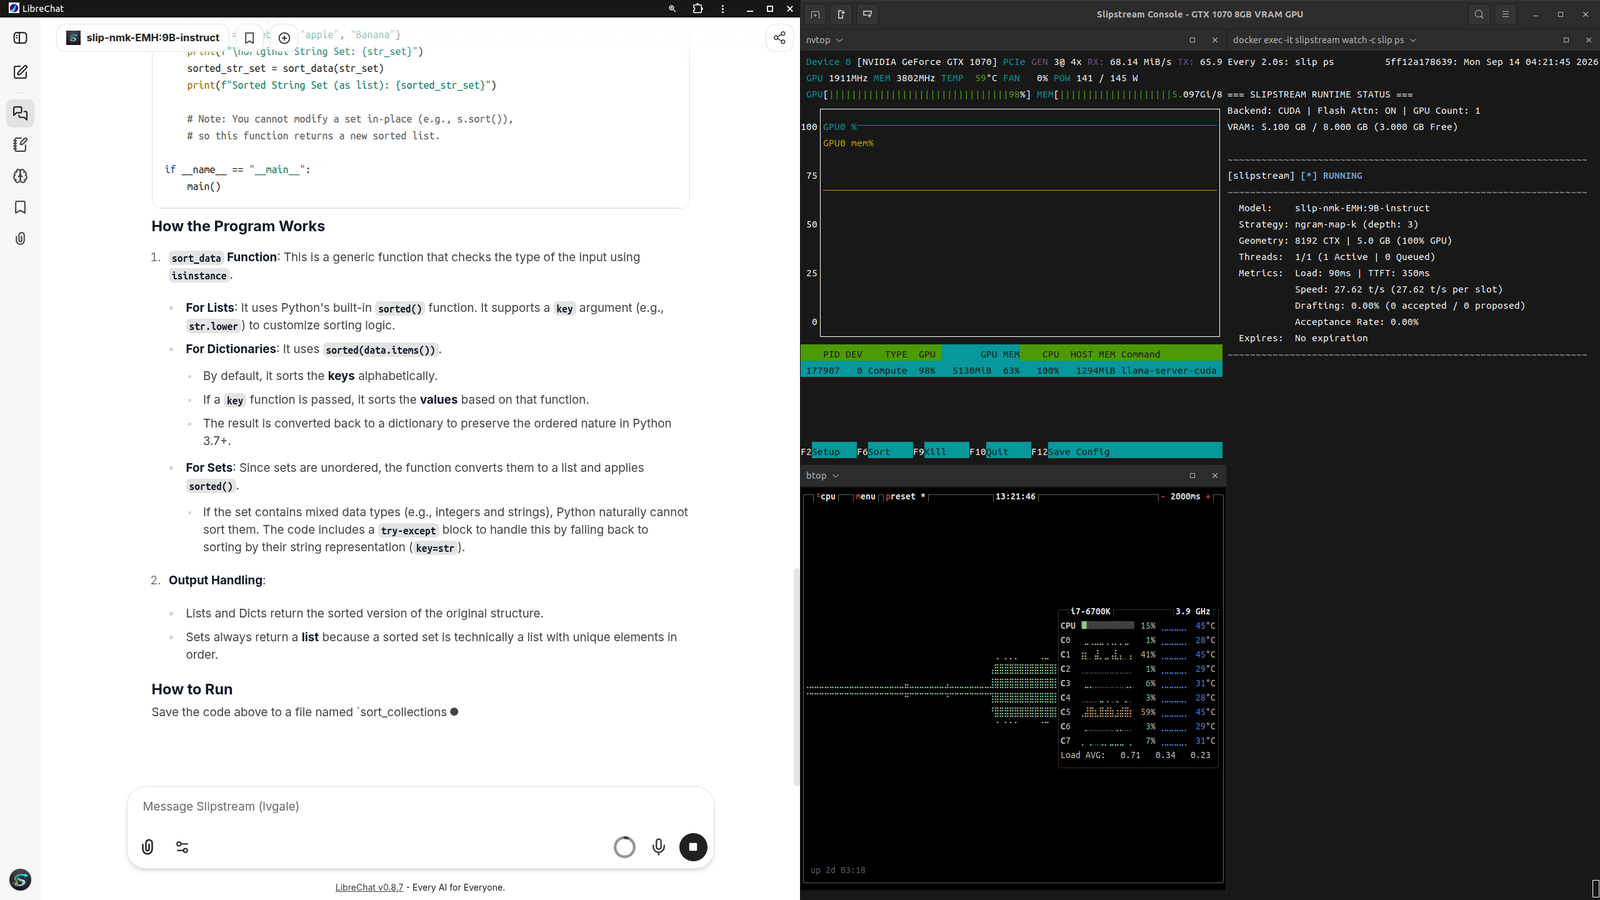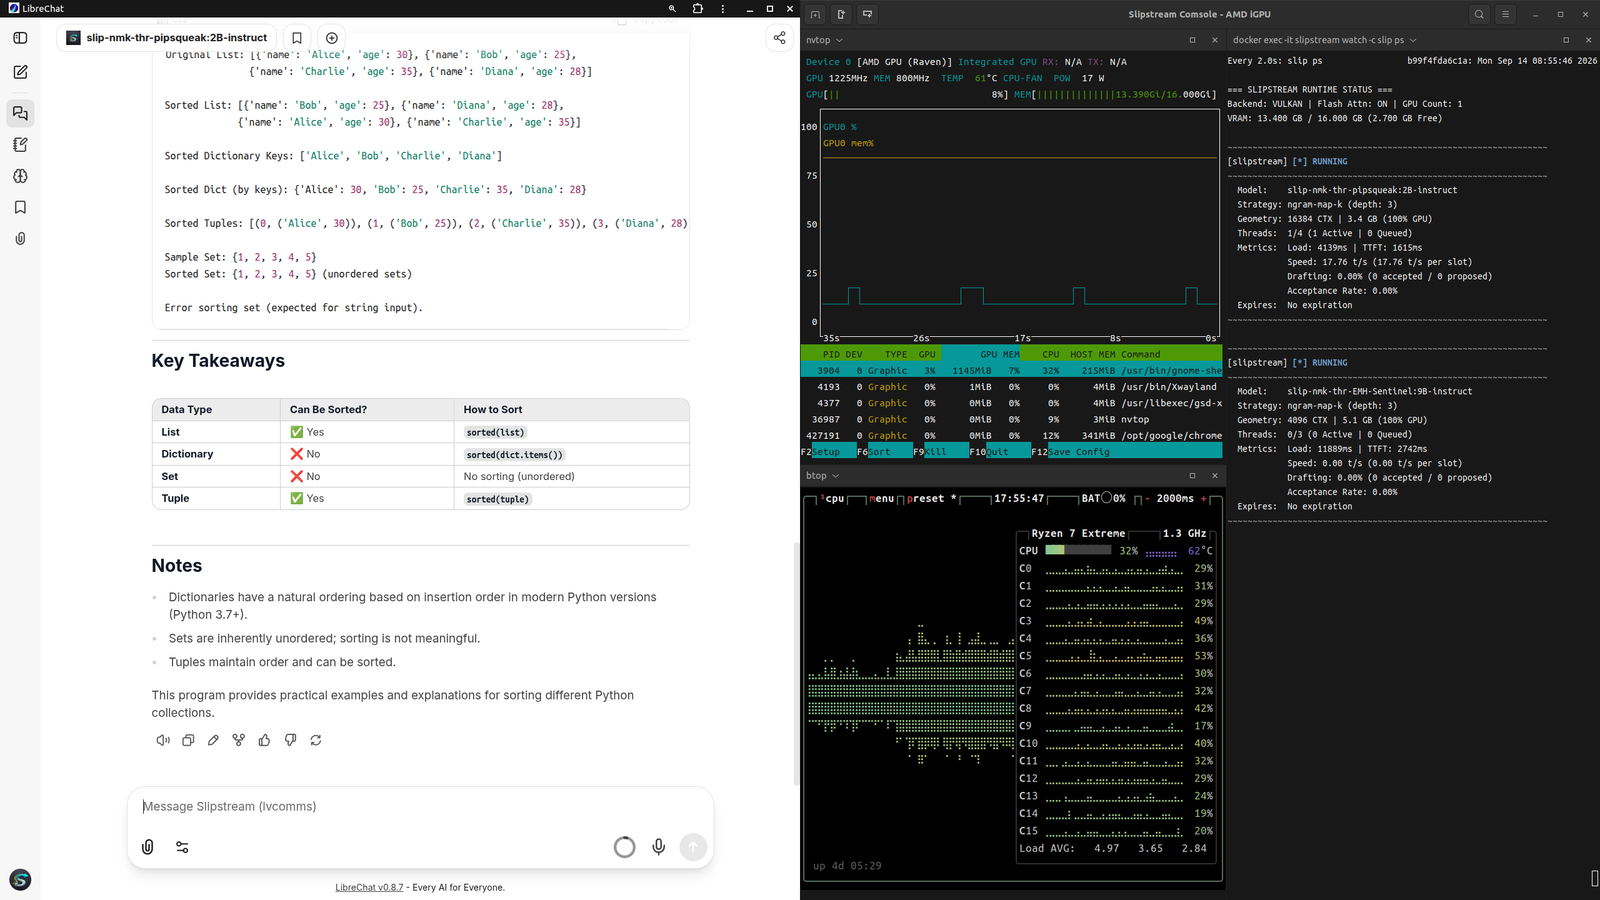
Speculative Orchestrator for Ollama & Llama.cpp
投機的オーケストレーター
Dynamic multi-instance orchestration engineered to handle high-velocity speculative decoding, routing, and memory teardown directly at the hardware edge.
ハードウェアエッジで高速度の投機的デコーディング、ルーティング、メモリティアドOWNを処理するように設計された動的マルチインスタンスオーケストレーション。
コアアーキテクチャ
高速度投機的デコーディング
Engineered for maximum throughput with intelligent token prediction and verification pipelines that minimize latency at the hardware level.
動的インスタンスルーティング
Real-time workload distribution across multiple LLM instances.
メモリティアドOWNエンジン
Aggressive memory reclamation and context management to maintain optimal performance during high-concurrency operations.
Ollama & Llama.cpp統合
Seamless orchestration layer for existing LLM inference frameworks. Drop-in enhancement without code modifications.
ハードウェアエッジデプロイメント
Zero cloud dependencies. Designed for on-premise and edge computing environments with strict sovereignty requirements.
主権AI
Full architectural control. No external telemetry, no data leakage, complete operational transparency for audit-critical deployments.
アーキテクチャノート
ガベージコレクションとドラフトモデル
When utilizing Slipstream's dynamic // DRAFT_MODEL tags for speculative decoding, be aware of current backend limitations. Ollama's native garbage collector does not cryptographically trace these dynamic dependency links.
Admin Warning: Running aggressive blob pruning operations on the host can result in the accidental deletion of draft models tethered via Slipstream. Native dependency checking will be available in future releases of the slip inspect feature.
スリップストリーム号
"Where are you going?"
「どこへ向かっているのか?」